Key Statistics
Our daily tracking produced these headline figures for open-source embedding and reranker models on Hugging Face. "Mid-March" means the week of March 15 to 21, 2026.
- all-MiniLM-L6-v2 was the most downloaded Hugging Face model of any type on all 231 days from Feb. 12 to Oct. 1, 2026.
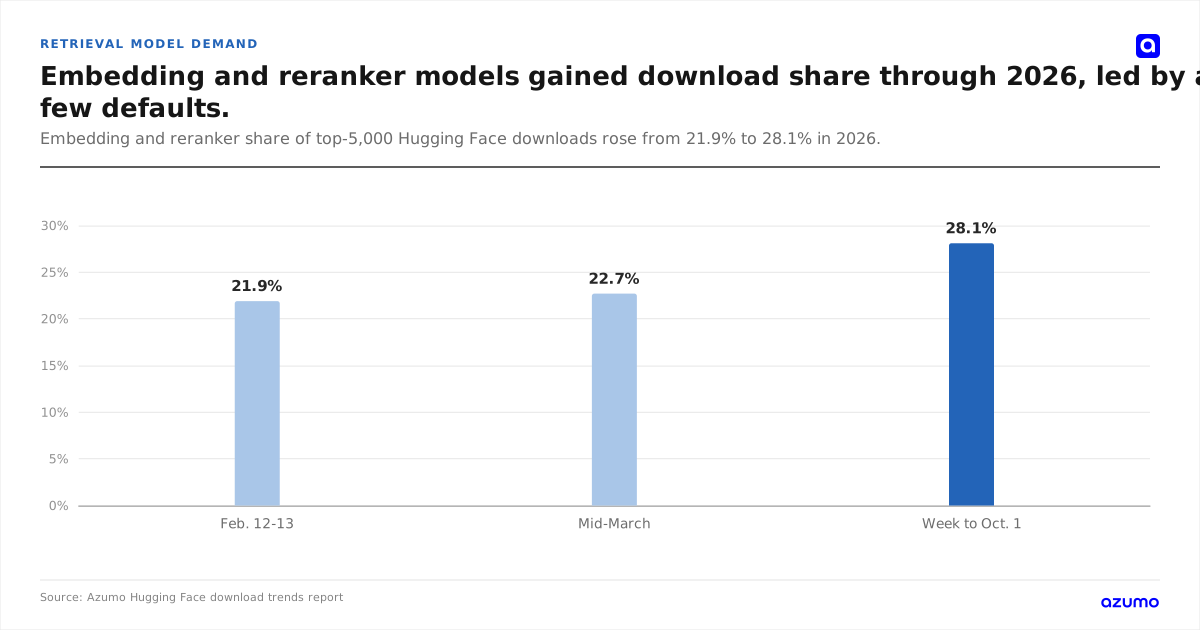
- Embedding and reranker models took about 28% of top-5,000 downloads in the week to Oct. 1, 2026, from about 8% of the slots.
- As of Oct. 1, 2026, five of the ten most downloaded models of any type were retrieval models, and three repos held half of the embedding and reranker category's downloads.
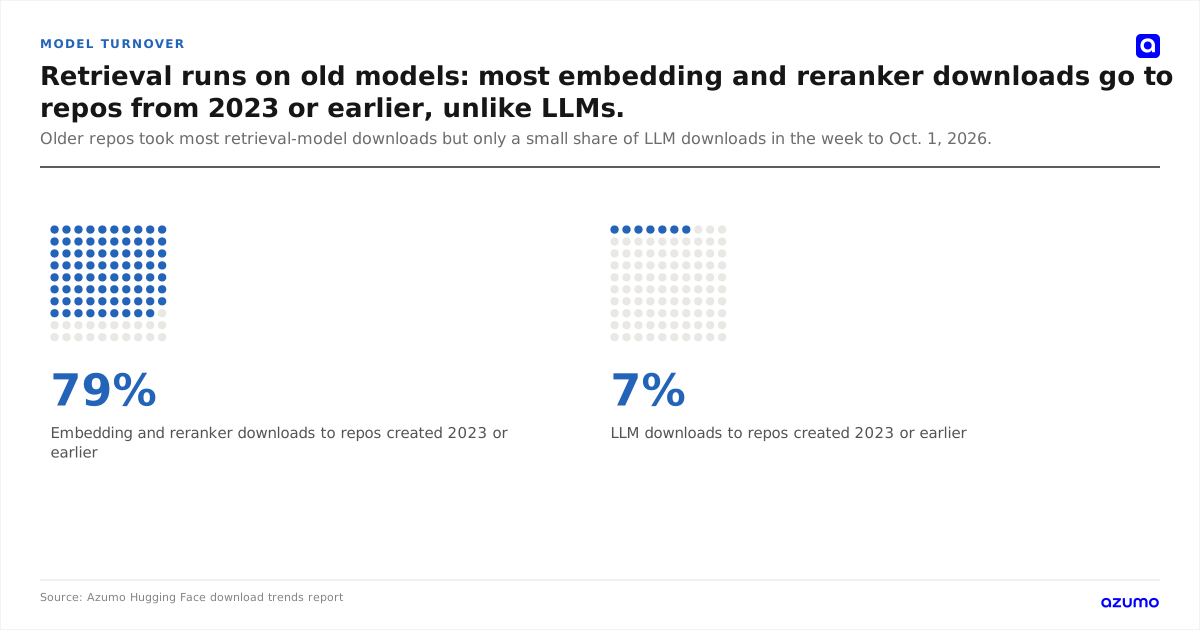
- About 79% of embedding and reranker downloads in the week to Oct. 1, 2026 went to repos created in 2023 or earlier.
- The largest embedding repo created in 2025 or 2026, Qwen3-Embedding-0.6B, held about 1% of the category's downloads as of Oct. 1, 2026.
- Rerankers rose from about 1.6% to 5.1% of all top-5,000 downloads between mid-March and the week to Oct. 1, 2026.
- BAAI's share of embedding and reranker downloads went from about 10% to 21% in our data to Oct. 1, 2026, counting models uploaded in 2024 or earlier.
- Apache-2.0 accounted for 71.4% and MIT for 24.3% of the most downloaded embedding and reranker models on Oct. 28, 2026.
Top 15 Open-Source Embedding Models on Hugging Face by Downloads
all-MiniLM-L6-v2 leads with 190.8M downloads in the 30 days to Oct. 28, 2026, more than three times the next embedding model. The table ranks the 15 most downloaded embedding and reranker models over that window, according to our live embedding and reranker download trends.
Read the table as a measure of adoption. Download counts include automated pulls by tools and test pipelines, which lift models that are fetched by default. Two makers hold most of the table: sentence-transformers, with four entries, and BAAI, the Beijing Academy of Artificial Intelligence, with five. Language coverage comes from each model's card.
all-MiniLM-L6-v2: The Most Downloaded Embedding Model on Hugging Face
all-MiniLM-L6-v2 recorded 190.8M downloads in the 30 days to Oct. 28, 2026. It ranked first among all Hugging Face models on every one of the 231 days we tracked. It is an English embedding model from sentence-transformers, released under Apache-2.0. Its counts include automated pulls by tools and pipelines, so part of its lead reflects how often software fetches it by default, not how many teams chose it.
BAAI bge-small-en-v1.5 and bge-m3: Why BAAI's Share Doubled
BAAI's share of embedding and reranker downloads went from about 10% to 21% in our data to Oct. 1, 2026. Over the same period, sentence-transformers fell from about 62% to 46%. Both figures cover models uploaded in 2024 or earlier, with converted copies left out.
bge-small-en-v1.5 is BAAI's most downloaded model, at 53.0M in the 30 days to Oct. 28, 2026. bge-m3 follows at 29.9M. bge-small-en-v1.5 was one of three models that climbed together from mid-April to late June, a pattern covered in the reranker section below. Our data does not break BAAI's gain down by model.
paraphrase-multilingual-MiniLM-L12-v2: The Most Popular Multilingual Embedding Model
paraphrase-multilingual-MiniLM-L12-v2 is the most downloaded multilingual embedding model in our data, at 38.7M downloads in the 30 days to Oct. 28, 2026. It ranks fourth overall. The next multilingual embedding models are bge-m3 at 29.9M and intfloat's multilingual-e5-small at 9.3M. Confirm language coverage on each model card before you rely on it.
all-mpnet-base-v2 and nomic-embed-text-v1.5: The Next Step Up From MiniLM
After all-MiniLM-L6-v2 and bge-small-en-v1.5, the next most downloaded English embedding models are all-mpnet-base-v2 and nomic-embed-text-v1.5. all-mpnet-base-v2, also from sentence-transformers, drew 18.9M downloads in the 30 days to Oct. 28, 2026. nomic-embed-text-v1.5, from nomic-ai, drew 12.2M. Neither figure measures retrieval quality, so compare them with MiniLM on your own documents before you switch.
Embedding and Reranker Models Take 28% of Hugging Face's Top-5,000 Downloads
Embedding and reranker models took 28.1% of top-5,000 Hugging Face downloads in the week to Oct. 1, 2026, from about 8% of the slots. LLMs (large language models) took 29.8% in the same week. Retrieval models come close to LLMs on volume with a much smaller number of repos.
The share rose through 2026. Embeddings and rerankers held 21.9% of top-5,000 downloads on Feb. 12 and 13, 22.7% in mid-March and 28.1% in the week to Oct. 1, according to our Hugging Face download trends report. As of Oct. 1, five of the ten most downloaded models of any type were retrieval models, and three repos held half of the category's downloads.
Volume this concentrated behaves like infrastructure. A search or RAG (retrieval-augmented generation) system loads its embedding model in builds, tests and deployments, and each fetch can count as a download. Our data cannot separate those automated pulls from deliberate use, so read the share as fetch volume.
Why the Most Popular Embedding Models Are Years Old
About 79% of embedding and reranker downloads in the week to Oct. 1, 2026 went to repos created in 2023 or earlier. For LLMs, the figure was 7%. Only 0.4% of embedding and reranker downloads went to repos created since Feb. 12, 2026.
Many of these models are older than their listed date. About 59% of embedding downloads sit on repos that carry Hugging Face's placeholder creation date of March 2, 2022, the earliest date the platform records.
Turnover is slow. Embedding models, like text classification, time series and translation models, now get 94 to 98% of their downloads from repos that were already in the top 5,000 in mid-March. For LLMs, the figure is about 57%.
New Embedding Models Gaining Traction in 2026
Repos created in 2025 or 2026 hold about 7% of embedding and reranker downloads as of Oct. 1, 2026. The largest, Qwen3-Embedding-0.6B from Qwen, holds about 1%, with 8.3M downloads in the 30 days to Oct. 28, 2026.
A few recent uploads have reached the top 5,000. According to our live trends, they include NVIDIA's Nemotron-3-Embed-1B-BF16 (uploaded July 14, 2026, with 297K downloads in the 30 days to Oct. 28), Google's embeddinggemma-2 (Sept. 14, 257K), NVIDIA's Nemotron-3-Embed-8B-BF16 (July 14, 149K) and Jina AI's jina-reranker-v3.5 (July 14, 115K). None is yet close to the older defaults.
Reranker Models Tripled Their Share of Hugging Face Downloads
Rerankers rose from about 1.6% to 5.1% of all top-5,000 Hugging Face downloads between mid-March and the week to Oct. 1, 2026. Within the embedding and reranker category, their share went from about 7% to 18%. On Oct. 28, 2026, rerankers made up 18.1% of the category's downloads and embedding models 81.9%.
What Is a Reranker Model and When Do You Need One?
A reranker is a model that re-sorts the results an embedding search returns. The embedding model finds a set of likely passages quickly. The reranker then scores each query and passage pair together and puts the best match first. In a RAG system, this step sits between retrieval and the language model that writes the answer. A reranker is worth testing when the right passage appears in your search results but not near the top.
A reranker works alongside the database that stores your embeddings. We compare the main options in our guide to vector databases for RAG.
Most Downloaded Open-Source Reranker Models
cross-encoder/ms-marco-MiniLM-L6-v2 leads with 70.7M downloads in the 30 days to Oct. 28, 2026. It accounted for about 60% of reranker downloads in our trend data.
The newest notable reranker in the top 5,000 is jina-reranker-v3.5, uploaded July 14, 2026, with 115K downloads in the 30 days to Oct. 28.
Why Three Retrieval Models Rose in Lockstep
Three models climbed together from mid-April to late June 2026: cross-encoder/ms-marco-MiniLM-L6-v2, BAAI/bge-small-en-v1.5 and BAAI/bge-reranker-v2-m3. They have stayed near those levels since. Their day-to-day changes track each other more closely than any other pair among models averaging over 3M downloads a month. That pattern fits one large consumer, such as a framework's default models. Our data cannot show who.
This matters for the headline figure. Without its two biggest gainers, ms-marco-MiniLM-L6-v2 and bge-small-en-v1.5, the embedding and reranker category's gain in share of top-5,000 downloads since mid-March is about 2 points, against 5 with them. Read both figures together.
Top Embedding Model Providers on Hugging Face: BAAI vs Sentence-Transformers
sentence-transformers held 45.0% of embedding and reranker downloads on Oct. 28, 2026, more than twice BAAI's 20.8%. cross-encoder, the account behind the ms-marco rerankers, held 13.0%.
The longer trend favors BAAI. On models uploaded in 2024 or earlier, with converted copies left out, BAAI went from about 10% to 21% of the category in our data to Oct. 1, 2026, and sentence-transformers fell from about 62% to 46%. In the three months to Oct. 28, every maker's share moved by less than one point.
Are Open-Source Embedding Models Free for Commercial Use?
Most of the leading ones are. Apache-2.0 accounted for 71.4% and MIT for 24.3% of the most downloaded embedding and reranker models on Oct. 28, 2026. Both are permissive licenses that allow commercial use. Our report places embedding models among the most permissively licensed model types on Hugging Face, at about 95%. These figures use the license declared on each repo, so confirm the terms on the model card before you deploy or redistribute weights.
How Accurate Are Hugging Face Download Counts?
Hugging Face download counts measure file fetches, not people or deployments. According to Hugging Face's download-count documentation, every GET or HEAD request to a repo's query file, by default config.json, counts as a download. The public count does not separate unique users from repeat requests, and, as our report notes, it includes automated traffic.
Embedding models are exposed to this. Their counts include automated pulls by tools and test pipelines, which lift models that are fetched by default.
Counts can also break. From June 10 to 19, 2026, almost every model's reported 30-day downloads fell by about a third within a few days, then recovered by June 20. Total 30-day downloads across the top 5,000 dropped from 2.67B to 1.80B while likes stayed unchanged. A smaller dip followed in August, from 3.01B on Aug. 5 to 2.75B on Aug. 12 and back to 3.00B by Aug. 16.
For these reasons, we compare shares rather than raw totals, state the time window for every figure and leave days with counting faults out of our share charts. Read every number here as fetch volume over a stated window.
How to Choose the Best Open-Source Embedding Model for RAG
Start with the most adopted model for your need, then test alternatives on your own documents. Adoption shows where most teams start, not which model fits your corpus.
Generalist embedding models are trained for broad use, so they can miss the terms that matter in your domain. Fine-tuning on your own data is the way past the defaults. Choosing an embedding model, a reranker and a database that work together is part of our RAG development services.
Methodology: How We Ranked Embedding Models by Downloads
We recorded the top 5,000 Hugging Face models by 30-day downloads every day from Feb. 12, 2026. From Feb. 14 to March 12, we kept only the top 1,000, and June 22 is missing. Up to Oct. 1, 2026, that came to 1,053,899 rows covering 13,182 models.
Each model is placed by its Hugging Face task tag. On our live pages, repos with "rerank" or "cross-encoder" in their name count as rerankers. Rankings use 30-day figures to Oct. 28, 2026 from our live embeddings page. Trend findings cover Feb. 12 to Oct. 1, 2026. For the report, we recomputed every finding with independent code, and reviewers then tried to disprove each one. The full method is in our Hugging Face download trends report.
Run Open-Weight Models Tuned to Your Own Data
The models in these tables are general-purpose defaults. They know nothing about your contracts, tickets or product terms. A model tuned to your own data is the next step.
Valkyrie by Azumo fine-tunes open-weight models on your data and runs them on dedicated hardware that we operate. You buy concurrent agents rather than tokens, so the bill is the same in a heavy month and a quiet one. Valkyrie serves OpenAI- and Anthropic-compatible endpoints, so most tools connect with one environment variable. You own the weights, and the service is SOC 2 certified.
Follow the defaults on our live embedding and reranker download trends, updated daily, read the full report, and see how Valkyrie works.
Frequently Asked Questions

About the Author:
Chief Technology Officer | Software Architect | Builder of AI, Products, and Teams
Juan Pablo Lorandi is the CTO at Azumo, with 20+ years of experience in software architecture, product development, and engineering leadership.