


The Best Models are
Domain Specific and Purpose Driven
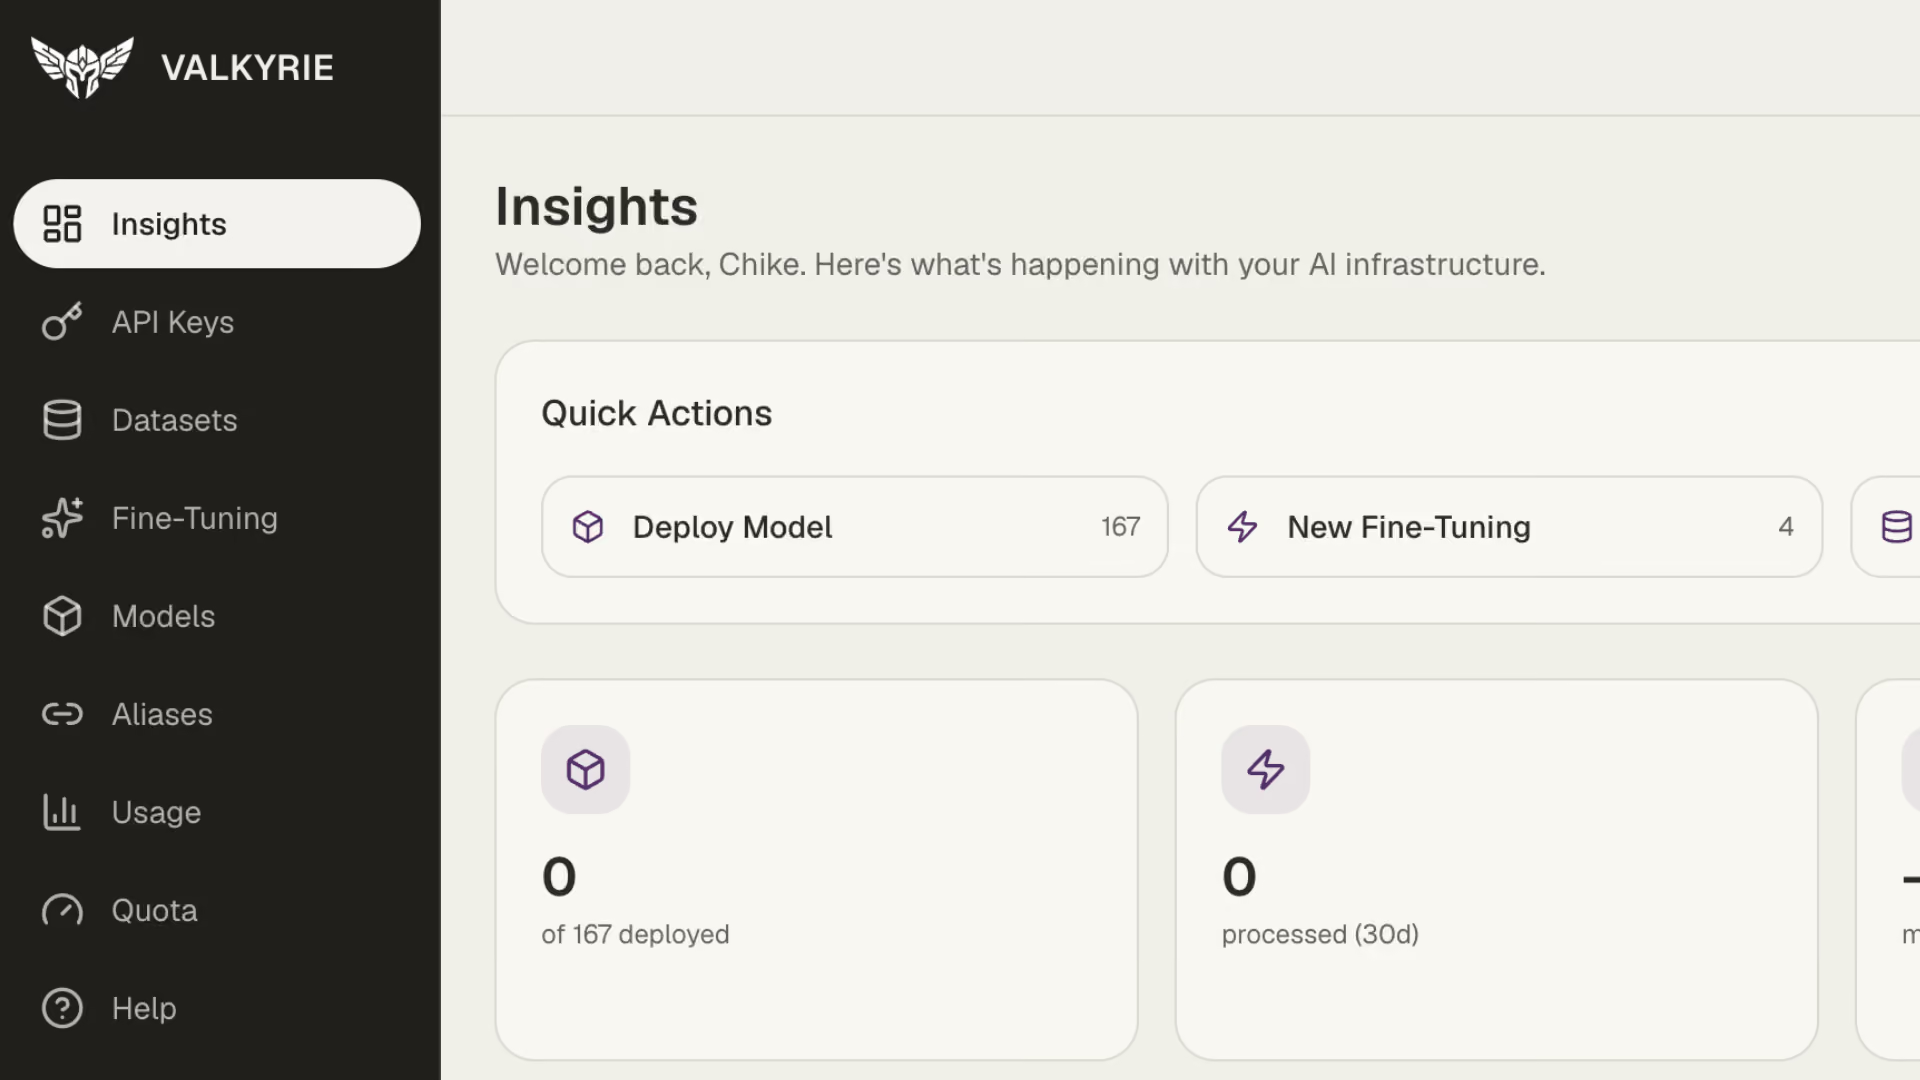
Valkyrie enables you to run open-weight AI agents fine-tuned on your data. You control the data and get predictable, consistent performance.
- SOC 2 Certified
- Harness Compatible
- 4.9 stars on Clutch
The Frontier Models' Commercial Approach Doesn't Work
Increasing Cost
Consumption pricing means the number tracks usage, but token cost vary and makes budgeting difficult.
Tokens Run Out
A weekly limit resets on Thursday and the work waits until then. The pace of work slows to a crawl.
Legal Says No
The data cannot leave the four walls of the business, so some logical use cases dont get built.
and then ...
the frontier model at the top of the benchmark is not the model you are running.
Not before.
Why Valkyrie
Your team uses frontier models every day. The real question is how you can control the bill and stay productive. Valkyrie gives your whole team an open-weight solution at a predictable price with predictable performance.
Pricey metered billing requires intense oversight.

Open-weight economics and control, with nothing to operate. Build without metered limits, and DevOps headaches
A flat price, but capped usage. Model behavior may change over time.
How Valkyrie Works
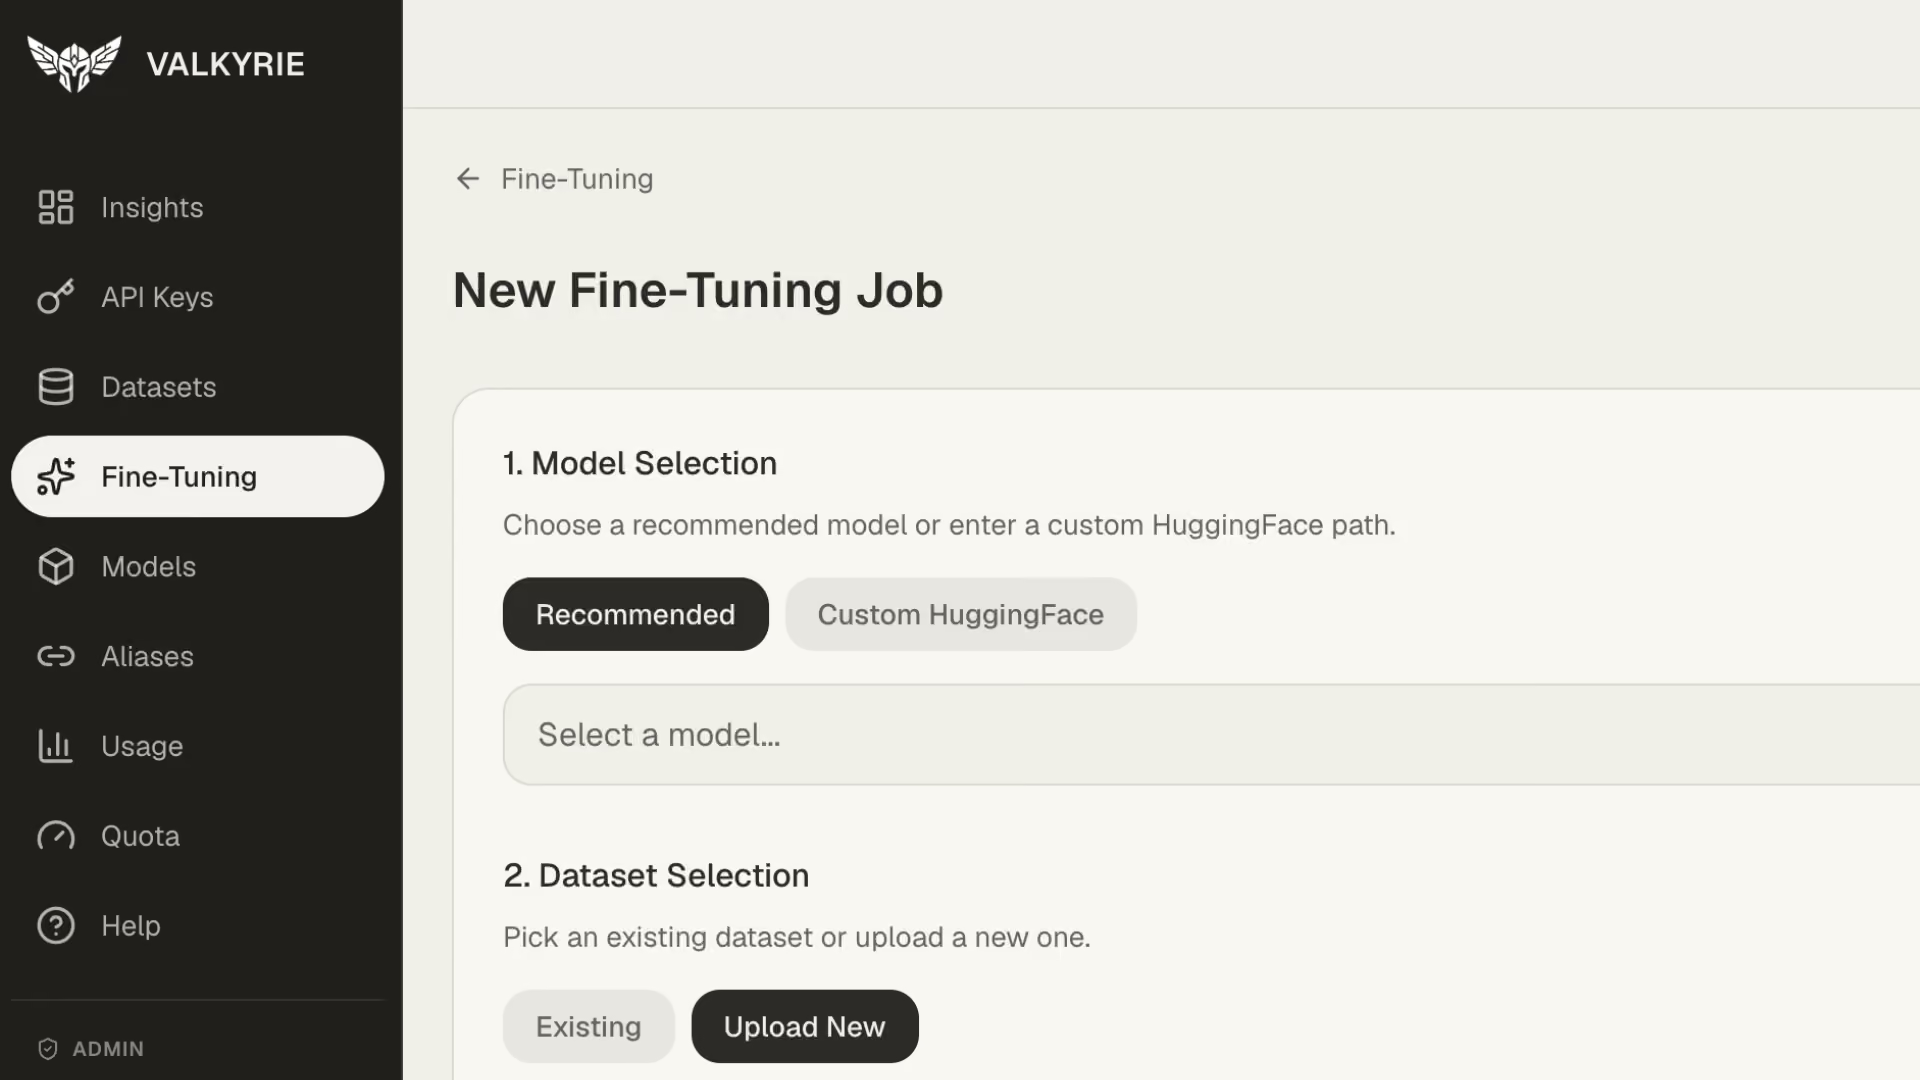
Valkyrie fine-tunes an open-weight model on your own data, runs it on hardware we operate, and serves it through the endpoints your product, agents and coding tools already speak. You own the weights. We operate everything underneath.
Fine-tune
We train an open-weight model on your own inputs and outputs, so it gets better at the job you care about rather than everyone's.
Valkyrie Runs it
Your model runs on dedicated hardware we operate. You buy concurrent agents, not tokens, so the bill is the same in a heavy month and a quiet one.
Connect
OpenAI and Anthropic compatible endpoints. Most tools connect with one environment variable and no code changes.
Your product
Your apps, through the OpenAI SDK
Agent workflows
Support ticket triage. Document Extraction. Fraud prevention.
Coding tools
Claude Code, Cursor, Codex, your CLI
Valkyrie by Azumo
Open-weight service
Choose Your Open Weight Model.
Valkyrie gives your team the power of open-weight models with enterprise-grade operations and guardrails so you can ship faster with confidence.


Private & Secure
Your code, your data. Always private
Predictable Pricing
One price per developer
Reliable by Design
High availability and support
Which open weight models get downloaded most?
We track the 5,000 most-downloaded models on Hugging Face every day, across LLMs, embeddings, speech, vision and more.
What changes when you switch
One price, every month
The monthly bill is identical in a heavy week and a quiet one. Finance can forecast it, and nobody has to ration a model to stay under a number.
No usage gates
No weekly ceiling and no throttle halfway through a task. Past your reserved agents the work queues rather than failing, and it never costs more.
Your instance and your data
A dedicated endpoint on hardware no other customer touches. Prompts and completions are not retained after the request unless you switch logging on yourself.
Pinned model versions
The version you deploy is the version you keep. When better weights ship we benchmark them against yours and send you the table. You decide whether anything moves.
Audited before it ships
Azumo's automated code audit runs against what the model produces, catching security, cost and architecture problems before they reach production.
LLM Fine-Tuning to Align Your Model to Your Needs
Pick a model, point at a dataset, set the epochs, start the job. No scoping call and no statement of work.
Access Valkyrie Your Way
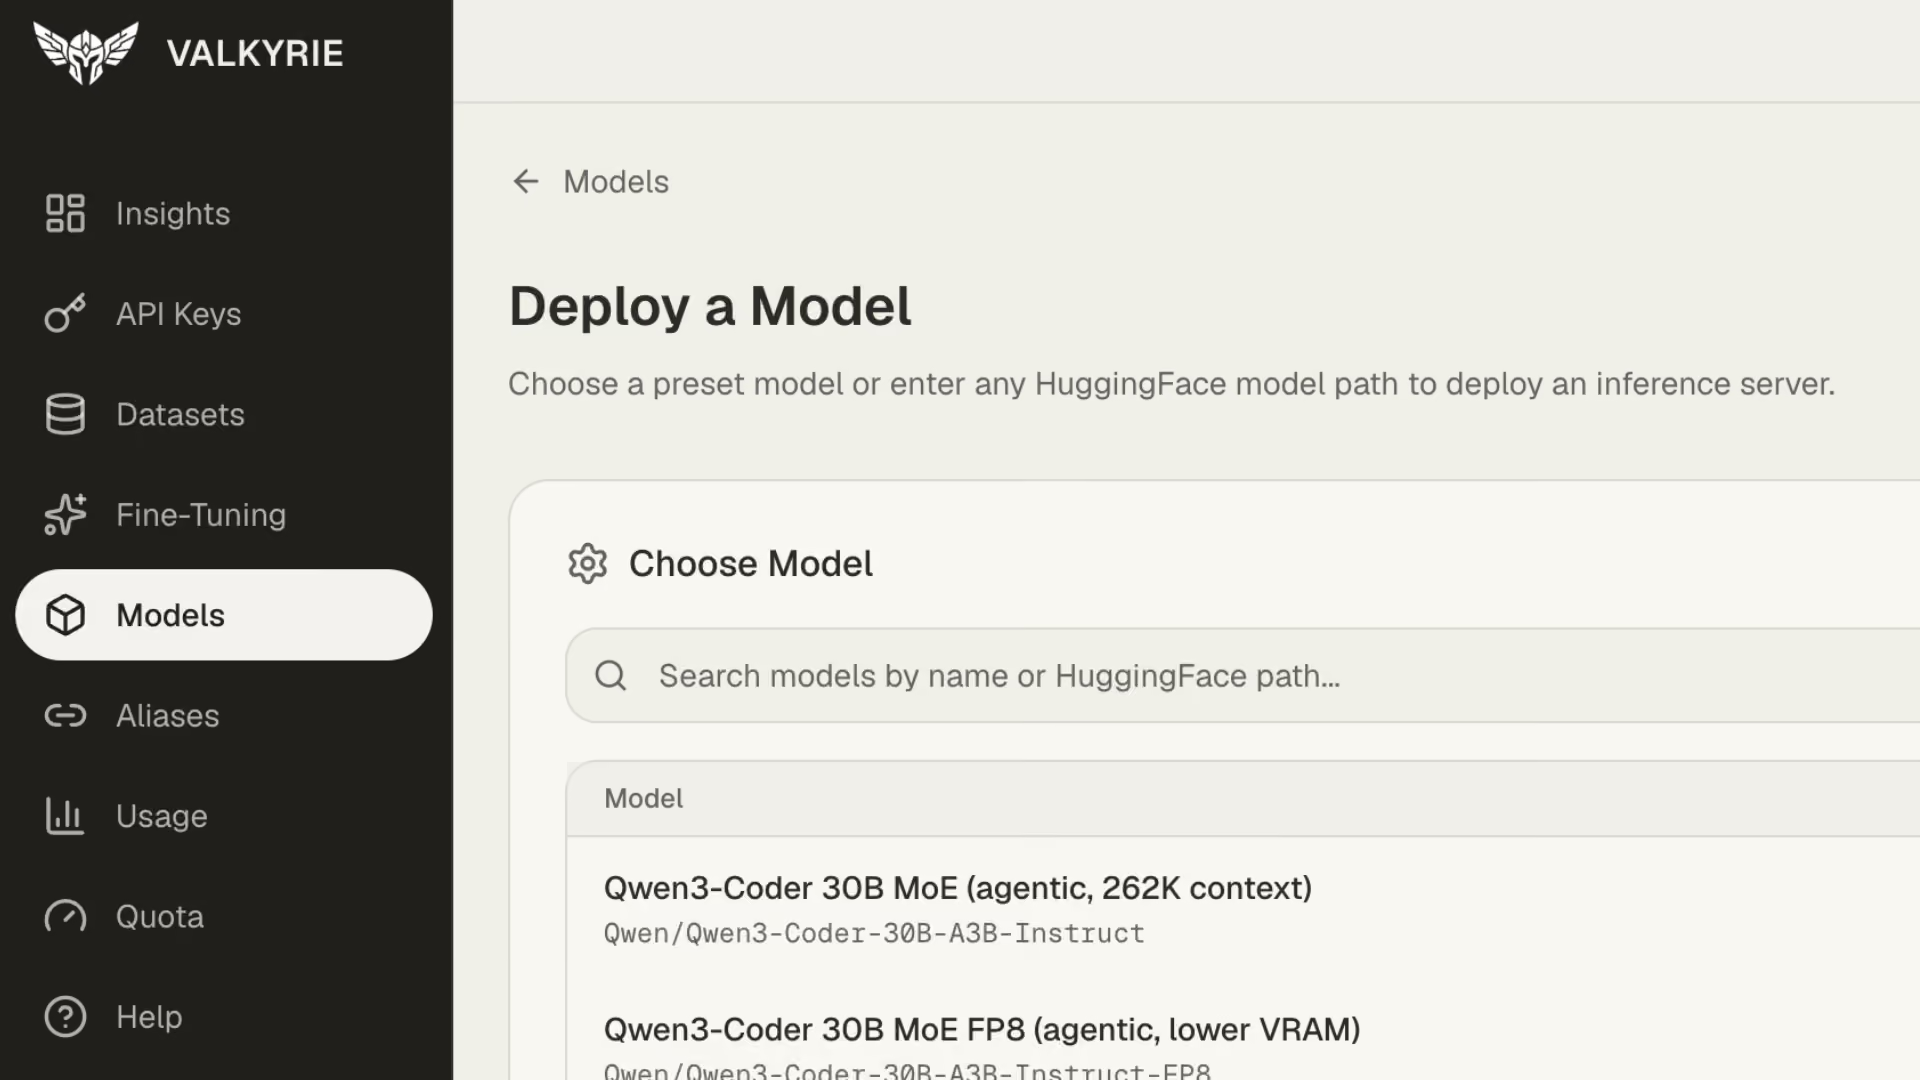
Deploy a model from the dashboard, then point your existing client at its endpoint. Valkyrie speaks both the OpenAI and Anthropic protocols, so most tools need one environment variable and no code changes.

Coding Agents
Claude Code, Cursor, Opencode, Pi, and Qwen Code all connect to a Valkyrie deployment. Claude Code takes the Anthropic protocol directly. The rest register Valkyrie as a custom OpenAI-compatible provider.
export ANTHROPIC_BASE_URL=
"https://valkyrie-back.azumo.com/acme/fast"
export ANTHROPIC_AUTH_TOKEN=
"vk_dep_..."
claude

OpenAI Client
Built on the OpenAI standard, so your SDKs and apps connect as they are. Point them at your deployment and go.

Valkyrie Dashboard
Deploy a model from Hugging Face or one you have fine-tuned, watch training jobs, read per-request usage, and manage keys and balance.
MCP Server
Deploy a model from Hugging Face or one you have fine-tuned, watch training jobs, read per-request usage, and manage keys and balance.
How your data is handled
Dedicated instances
Your model runs on hardware allocated to you. It is not a namespace on a shared endpoint, and no other customer's traffic touches it.
Nothing retained
Prompts and completions are discarded when the request finishes. Logging is off until you turn it on, and you set the retention window.
Your data trains nothing else
Your traffic never trains a model another customer can reach. Improving your own model runs on your data, in your instance, and you approve each cycle.
You own the weights
A model we fine-tune on your data is yours. Export it and run it elsewhere whenever you want. It also means we are not a single point of failure.
Defined cost.
Better performance.
You buy concurrency rather than consumption, so the number is the same in a heavy month and a quiet one. And because the model is trained on your work instead of everyone's, it comes out better on the job you care about.